AI is dynamic.
Its infrastructure
should be too.
The GPUs were always there. Atom puts them to work
Built for the stack you already run.
 vLLM
 SGLang
 TensorRT-LLM
 Dynamo
 Kubernetes
Usage changes.
GPU capacity
stays locked.
Traffic fluctuates. Models use resources unevenly. Fixed allocations leave capacity underused, even while GPUs are working.
Infrastructure that
flows with
demand.
Atom enables your AI workloads to scale horizontally and vertically with demand, while meeting your SLAs.
Reliable · Seamless · Fast
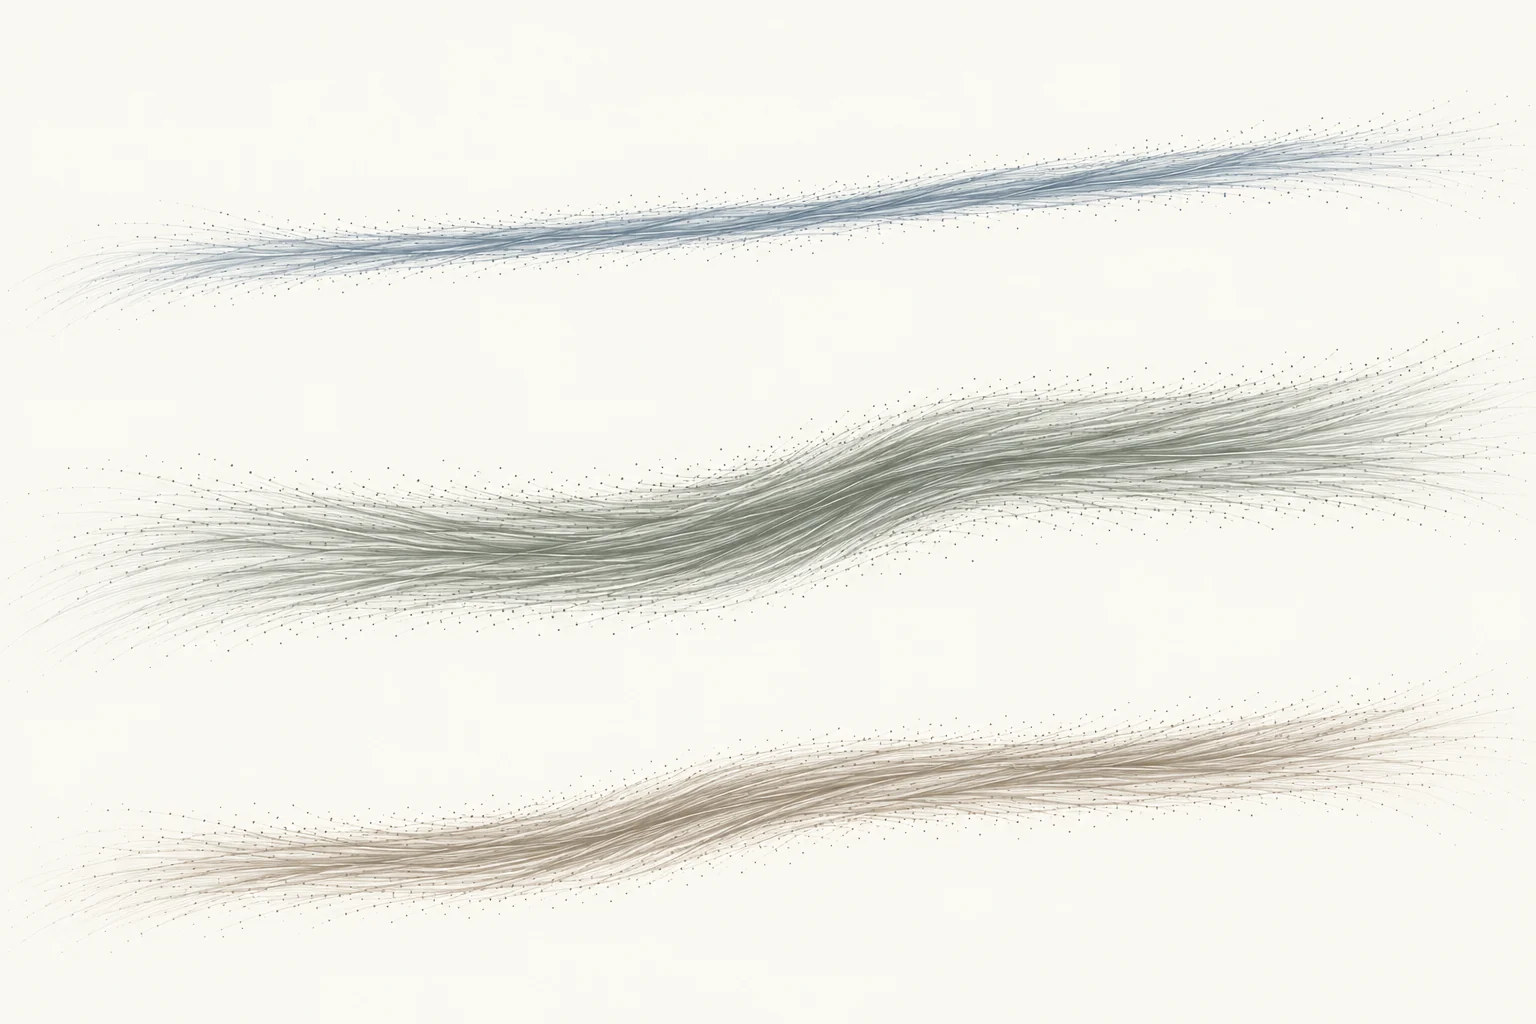
Same workloads. More room.
- Workload A
- Workload B
- Workload C
- Allocated capacity
Three active workloads with changing demand. The gold lines labelled Allocated to A, B and C show each workload's fixed capacity. Space above each wave remains reserved for that workload.
The same three demand patterns, on the same resource and time scales, share adaptive capacity. The gold boundary follows combined demand, leaving room for other work.
Performance that
keeps adapting.
Get more from the same GPUs as traffic and model needs change.
- request capacityvs. Disaggregated serving, within SLA
- 2–3×
- more workRun more jobs on spare capacity.
- 35–50%
For serving across different SLAs, multi-model workloads, agents, and background jobs.
Any model.
Ready in seconds.
Up to
63×
faster cold starts
| Model | Before | With Atom | Faster |
|---|---|---|---|
| Kimi K3 | 23.3 minutes | 40 seconds | 35 times faster |
| GLM-5.3 | 24.2 minutes | 25 seconds | 58 times faster |
| Kimi K2.6 | 24.6 minutes | 29 seconds | 51 times faster |
| DeepSeek V4 Pro | 22.2 minutes | 21 seconds | 63 times faster |
| Qwen3-235B-A22B | 5.5 minutes | 16 seconds | 21 times faster |
| gpt-oss-120b | 2.7 minutes | 3.3 seconds | 49 times faster |
| Llama-3.1-8B | 1.4 minutes | 2.2 seconds | 38 times faster |
| Qwen3-Next-80B-A3B | 3.5 minutes | 8.5 seconds | 25 times faster |
Distributed serving, ready in seconds.
20 seconds to start a disaggregated serving setup.
Your stack, unchanged.
Atom works beneath your existing serving stack.
- No application changes
- No model changes
- No container changes
- SOC 2 certified
- ISO 27001 certified
See what your
GPUs can do.
Get early access to Atom for your workloads.